Outbound playbook
The Zero-Touch Outbound Architecture: Building an Engine That Generates Pipeline
1. What is zero-touch outbound? 2. Why do AI SDR pilots fail? 3. Which signals are worth watching? 4. Why one signal isn't enough 5. What are the five layers? 6. How does the loop work end to end? 7. What does it cost by hand? 8. When is it safe to turn it on? 9. FAQ
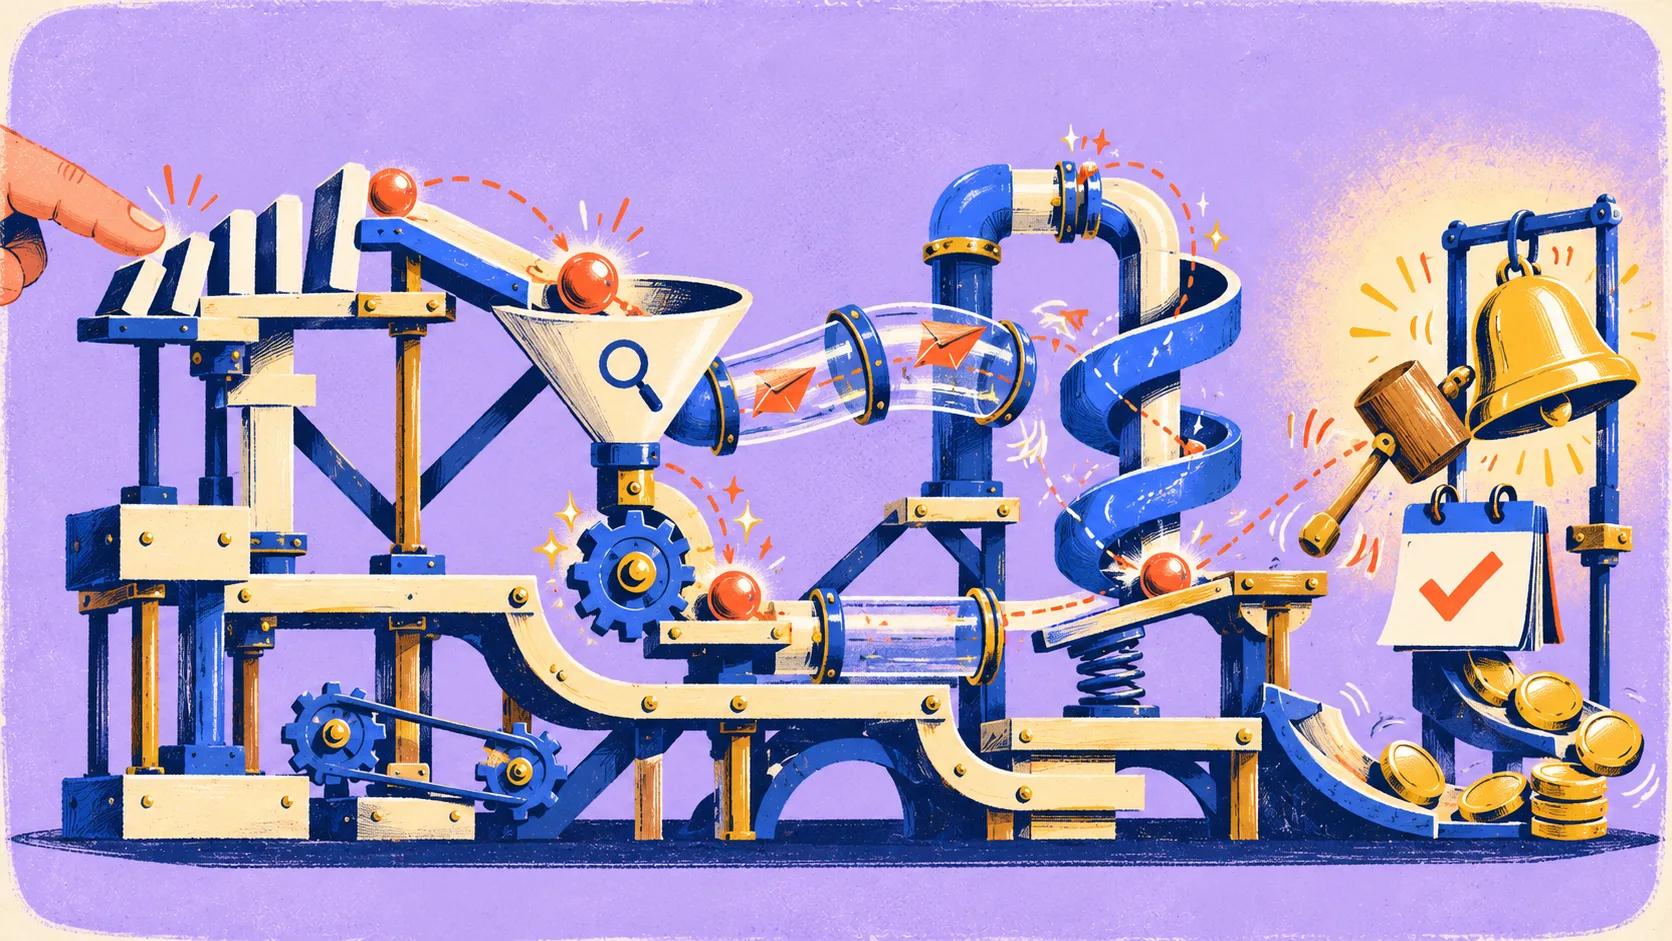
Zero-touch outbound means no manual toil, not no humans. Software watches for real changes at your target accounts, decides which ones deserve a message, and sends it inside limits you set.
Most AI SDR pilots fail because teams build the sending first and the seeing last. This post lays out the order to build it in, the numbers behind why, and what to check before you let anything send on its own.
| Figure | What it means | Type |
|---|---|---|
| 0.10% | Spam-complaint rate Google tells senders to stay under | Google sender guideline |
| 0.30% | The rate Google says to never reach | Google sender guideline |
| 40-60% | Of AI SDR pilots reported paused within 90 days | Vendor-reported estimate |
Read this before you copy the numbers
- Most figures here are vendor-reported or come from third-party analyses. They are not Outbird data, and each one is linked in Sources.
- The deliverability limits (0.10% and 0.30% spam complaints) come from Google's own sender guidelines.
- Failure rates like "40-60% of pilots" and "50-70% churn" are repeated across vendor blogs and their methods aren't public. Treat them as estimates, not facts.
- The only Outbird numbers are from our manual test: about 200 accounts, one team, 20 days. It is not a benchmark.
What is zero-touch outbound?
Zero-touch outbound, also called autonomous outbound, is an outbound system where software does the watching, filtering and drafting, so nobody does manual research or list building. A person still sets the rules and owns the conversations. It is a set of layers you build, not a tool you switch on.
The trigger is what we call a buying moment: a real change at a prospect's company, caught while it is still recent. The system's job is to notice moments, decide which ones matter, and stay quiet the rest of the time.
Read "zero-touch" as zero manual toil, not zero humans. A system with nobody checking it is how teams find out about a burned domain after the damage is done. The goal is people doing the judgment work and software doing the repeatable work. The system can run overnight, but someone still has to own the rules.
Why do AI SDR pilots fail?
They scale volume before they can see what that volume is doing. Fast sending to an old list with thin personalization produces bounces and spam complaints, and mailbox providers punish both. A better language model on the same pipeline doesn't fix it. The defect sits before the writing (who you pick, and when) and after the sending (what you measure).
| What is reported | Figure | Source |
|---|---|---|
| AI SDR pilots paused or shut down within 90 days | 40-60% | FirstSales |
| Deployments capped by domain-reputation damage within 90 days | about 47% | Laxis |
| Annual churn of AI SDR tools | 50-70% | UserGems, as cited by Autobound |
These are vendor-reported estimates and the methods behind them aren't public. The pattern is consistent, but the exact percentages are not settled.
The deliverability limits are real
Google's sender guidelines tell senders to keep the spam rate shown in Postmaster Tools below 0.10% and to avoid ever reaching 0.30%. Yahoo names the same 0.3%. The formal bulk-sender rules start at 5,000 or more messages a day to Gmail, but even below that, high complaint rates still hurt where your mail lands.
At 0.30%, three people in a thousand hit "Report spam". That is easy to reach when the recipient has no idea why you wrote to them.
Why template mail gets caught
Industry write-ups report that mailbox providers detect near-identical message bodies sent at scale. "Hi {{first_name}}, I noticed {{company}} is growing" produces the same body thousands of times. Swapping the name and company doesn't change the pattern.
Why static lists decay
A contact list is a snapshot. People change roles, companies change tools, and mailboxes get closed. A valid email address proves a mailbox exists. It says nothing about whether its owner has a problem you solve this quarter.
Which signals are worth watching?
Not all of them. An analysis of 1 million B2B software purchases found a wide gap between the strongest and weakest signals. Read the label carefully: the figure is how much more software a company bought afterwards, not how likely it was to buy your product.
| Signal | More software purchases afterwards |
|---|---|
| Enterprise AI tool adoption | +46% |
| Headcount growth of 20%+ | +38% |
| Recent software purchase | +38% |
| VP-level hire | +28% |
| Funding round | +25% |
| New office | +11% |
| Job-posting increase | +7% |
Bloomberry analysis of 1M B2B software purchases (March-September 2025), companies with 200-1,000 employees, as published by Bloomberry and republished by Prospeo. A correlation, not proof of cause.
Job postings are the signal almost every tool tracks by default, and they are the weakest on the list. A funding round is a press release every competitor also sees. The lesson isn't to track more signals. It is to pick the four or five that fit what you sell and ignore the rest. For how fast a signal goes stale, read How Long Does a Buying Signal Last?
Why one signal isn't enough
A single signal is a reason to keep watching, not a reason to send. When two or more independent sources point at the same problem, that is a moment worth acting on. Signal-stacking guides make the same point and suggest requiring two or three signals before outreach.
Here is what that looks like (an illustrative example, not a real account):
- Source A: a founder says on a podcast that onboarding new customers is the current bottleneck.
- Source B: three recent reviews of the company's product mention a three-week setup.
- Check: different publishers, different authors, different weeks, same problem.
That is no longer a press release. It is a problem the company has acknowledged in public, and it is recent. This is the judgment Outbird makes for you: it sorts each change into act, watch or ignore instead of messaging on everything it sees.
| Blasted mail-merge | Moment-based message | |
|---|---|---|
| Trigger | A list upload | A recent, relevant change |
| Opening line | "Hi {{first_name}}, saw {{company}} is growing fast!" | Names the specific public event |
| Evidence | None | Public sources you can point to |
| Structure | Identical across thousands of sends | Different for each moment |
| Value claim | Generic ("improve efficiency") | Tied to the problem they stated |
| Why they got it | No idea | They recognise their own public words |
× Mail-merge"Hi Priya, saw Acme is growing fast! We help teams improve efficiency. Free for a call this week?"
✓ Moment-based (illustrative)"Hi Priya, I heard you say on a recent podcast that onboarding is your bottleneck, and a few reviews mention a three-week setup. How are you handling that handoff today?"
The second one isn't better personalization. The relevance comes from the trigger, not from the copy. You can see what these moments look like in the Outbird Library.
What are the five layers of zero-touch outbound?
Build them bottom-up. Most teams build top-down: sending volume first, guardrails after the first incident, visibility once the domain is already hurt. The layers below borrow their framing from how site-reliability engineers run software. It is a way of thinking, not an Outbird product spec.
| Layer | What it does | What goes wrong without it |
|---|---|---|
| 0. See | Ingests public changes continuously, timestamped and source-attributed | You act on stale or single-source signals and can't tell why a message worked |
| 1. Automate the routine | Verification, deduplication, suppression lists, CRM cross-checks | People do work with one right answer, and mistakes slip through |
| 2. Limits that act on their own | Thresholds that pause sending automatically | Someone spots the damage in a weekly meeting, after it is done |
| 3. Isolate cold sending | Keeps cold mail off your primary domain, with per-mailbox caps | One bad week damages your invoices and customer email |
| 4. Humans govern | People own the rules, the edge cases and the conversations that matter | The system drifts and nobody audits it |
Layer 0: See before you send
Monitoring tells you something broke. Observability tells you why a buyer looks ready now. That needs continuous, timestamped, source-attributed ingestion of public changes: review-site activity, changelogs and release notes, job posts, podcasts, launches and public posts. A weekly CSV export is not that.
Layer 1: Automate the routine
If a task has one correct answer a machine can compute, automate it: email verification, deduplication, suppression-list checks, CRM cross-referencing, time zones. If it needs judgment about strategy, hand it to a person.
Layer 2: Limits that act on their own
Instead of someone checking a dashboard, thresholds become automatic actions. These are illustrative starting points to adjust, not Outbird defaults:
| Metric | Example threshold | Action |
|---|---|---|
| Hard bounce rate | Above about 2% | Pause the sequence |
| Spam complaint rate | Approaching 0.10% | Pause the domain and alert a person |
| Daily cold sends per mailbox | A low cap (reports cite roughly 25-50) | Queue the overflow for tomorrow |
| Reply rate | Far below your own baseline after a fair sample | Stop the template and review it |
Layer 3: Isolate cold sending
Cold outreach shouldn't go out from your primary domain, because that domain carries invoices, support replies and customer email. Use separate sending domains, fully authenticated with SPF, DKIM and DMARC, and warm them up before ramping. One 2026 report puts inbox placement at about 51% for domains warmed under 30 days and about 91% after 90 days or more (Laxis). Add capacity slowly instead of pushing more volume through one mailbox.
Layer 4: Humans govern
People review the rules themselves, decide edge cases, change the ICP and messaging boundaries, and own every conversation heading toward a meeting. FirstSales reports that the pilots which survive past 90 days almost all keep a person in the approval loop on every send.
One caveat: this is written from an email point of view. LinkedIn, X and WhatsApp each have their own limits and rules, so check the terms of every channel and what your tool actually does on it.
How does the loop work end to end?
- Watch. Collect public changes continuously from the places your ICP shows up. Coverage sets the ceiling, because nothing downstream can recover a signal you never saw.
- Judge. Decide whether a change is relevant to what you sell and whether more than one source agrees. The answer is act, watch or ignore, and most of the time it isn't "act".
- Write. Draft from the evidence, not from a persona template. Every sentence should trace to a public source, and a line you can't ground gets cut. No generic flattery.
- Send inside your limits. Vary the structure, ramp volume slowly, and stop on a breach before the next send, not after the next meeting.
- Handle replies. Sort by intent, answer in your own voice, suppress unsubscribes immediately, and send complex or high-value questions to a person with the context attached.
Where Outbird fits
Outbird is built around this order: the moment first, the message second. It watches your accounts continuously and judges each moment as act, watch or ignore. It builds familiarity first with comments and follows on LinkedIn and X, then drafts the message for your review. Replies from email, LinkedIn and WhatsApp land in one inbox, with drafts written in your voice and ready to edit, and Conversation Intelligence can tell when saying nothing is the smarter reply. A daily brief gathers the context.
To see how this differs from agent-style tools, read Outbird vs AI SDR agents, or look at the product page.
What does it cost to run outbound by hand?
In our manual test, watching about 200 accounts took 4-5 hours a day for 20 days. That is roughly 80-100 hours for nearly 12 meetings, or about 7-8 hours of work per meeting. It was one team and one customer profile, so treat it as one data point, not a benchmark.
Those hours are what the first layers of the stack should take over: checking accounts, researching context and drafting. The hours that should stay human are the rules, the edge cases and the conversations. Whatever tool you use, measure your own hours per meeting before and after. The full walkthrough of the manual test is in How to Build a B2B Outbound Lead Generation System From Zero.
When is it safe to turn on autonomous sending?
When all four of these are true. If any one is missing, keep sending manual: visibility first, automation second.
- Two independent signal sources. You ingest at least two kinds of public signal continuously, such as review activity plus podcast or changelog data, so you can check whether sources agree.
- Limits that are live and tested. Cause a deliberate test breach and confirm sending really pauses.
- Isolation is finished. Cold mail goes out from separate sending domains that are authenticated, warmed and capped, never from your primary domain.
- A person approves at first. Start in review mode and loosen it only after you have read the results.
Failed AI SDR pilots tend to share one pattern: the money goes into the top of the stack (writing, volume, sequencing) while the bottom (visibility, limits, isolation) is missing. The fix isn't a better tool at the top. It is building in the right order, and accepting that a system that sends less, only when something real has changed, can beat one that sends everything.
FAQ
What is zero-touch outbound?
Zero-touch outbound, also called autonomous outbound, is an outbound system where software watches for real changes at target accounts, decides which ones deserve a message, and drafts or sends it inside limits a person sets. It is built in layers, not bought as a single tool.
Why do AI SDR pilots fail?
Most scale sending before they can see results. Vendor reports estimate that 40-60% of pilots are paused or shut down within 90 days (FirstSales), though the method behind that figure isn't public. The common thread is volume without visibility, limits or isolation.
Does zero-touch outbound replace SDRs?
It replaces repeatable work such as research, verification and drafting. It does not replace judgment about strategy or the conversations that lead to a meeting. Teams that try to remove people entirely tend to repeat the failed-pilot pattern.
How is a buying-moment approach different from Clay or Apollo?
Clay and Apollo are strong at data and list building, which helps you answer who you can contact. A moment-based approach adds when: it looks for a recent change that makes outreach relevant now, and decides whether to act. The two can work together.
How do I avoid burning my sending domain?
Keep cold mail off your primary domain, authenticate your sending domains with SPF, DKIM and DMARC, warm them up, cap daily sends, and keep spam complaints below 0.10%. Pause automatically when a limit is breached.
Is Outbird zero-touch?
It takes over the manual work of watching, researching and drafting, but it isn't zero humans. Outbird isn't built for teams that want zero human judgment. It drafts outreach for your review, and you stay in charge of who you target and what gets sent. Book a demo or get early access to see it on your own ICP.
Read next How to Build a B2B Outbound Lead Generation System From Zero →
Figures in this post are vendor-reported or come from third-party analyses, except where we say they come from our own test. Check each one against its source before you rely on it. Last checked October 11, 2026.
Sources
- Google email sender guidelines: spam rate below 0.10%, never reaching 0.30%; authentication; bulk-sender threshold of 5,000 messages a day.
- Yahoo sender best practices: spam rate below 0.3%.
- Bloomberry: 1M software purchases and buying intent signals, republished by Prospeo.
- FirstSales: AI SDR pilot post-mortem: 40-60% of pilots paused or shut down within 90 days; human approval in surviving pilots.
- Laxis: State of AI SDR 2026: about 47% capped by domain-reputation damage; warm-up and inbox placement figures.
- Autobound: AI SDR vs human SDR: 50-70% annual churn, attributed to UserGems.
Share this article
Keep reading
Is a ChatGPT Visit a Buying Signal?Timing · Oct 4, 2026 · 5 min read How Long Does a Buying Signal Last? (Why Sources Disagree)Timing · Sep 28, 2026 · 10 min read Context Before Outreach: Why Strangers Get Ignored (And How to Stop Being One)Warm outreach · Sep 24, 2026 · 4 min read